| How you install it | Signed, notarized Mac app (DMG or Homebrew cask); no Python source | Signed, notarized Mac app or install script; no Python source | Signed, notarized Mac app with Python inside, or pip source | Homebrew or pip (Python); a separate signed desktop app source | Signed, notarized Mac app (DMG or Homebrew cask) with Python inside source |
|---|
| Model formats | GGUF and MLX, from one server source | GGUF and MLX (imported into its own store) source | MLX only source | MLX only source | MLX only source |
|---|
| OpenAI Chat Completions and Responses | Both source | Both (Responses without stored state) source | Both source | Both source | Both source |
|---|
| Anthropic Messages (Claude Code) | Yes, with count_tokens source | Yes, without count_tokens source | Yes, with count_tokens source | Yes, with count_tokens source | Yes, with count_tokens source |
|---|
| API key | On from the start source | None for the local server source | Asked for by the app's setup; off for the plain server source | Off unless set (the desktop app makes one) source | Off unless set source |
|---|
| Requests from web pages | Refused unless you allow an origin source | Only from this Mac's own pages and apps source | Any site (CORS *), changed only in settings.json source | Any site (CORS *) unless --cors-origins source | Any site (CORS *) source |
|---|
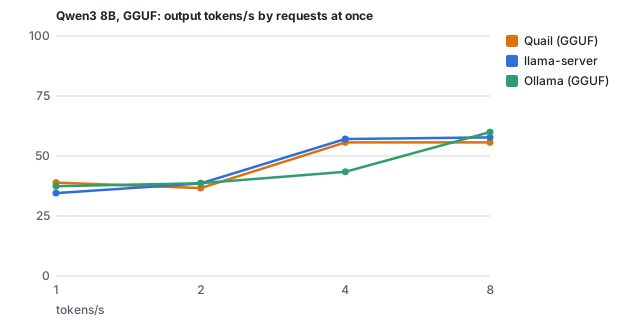
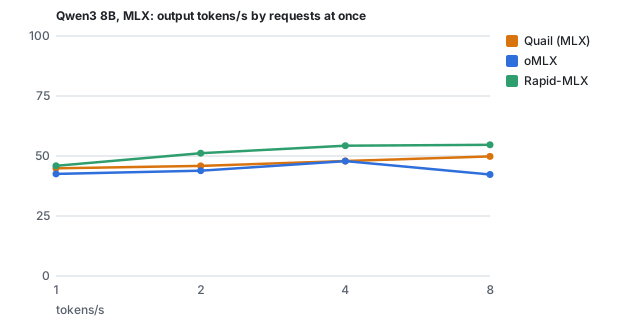
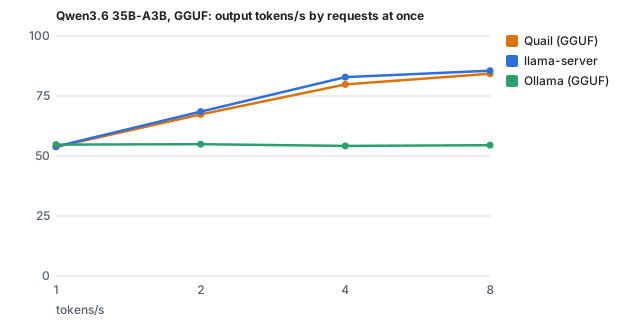
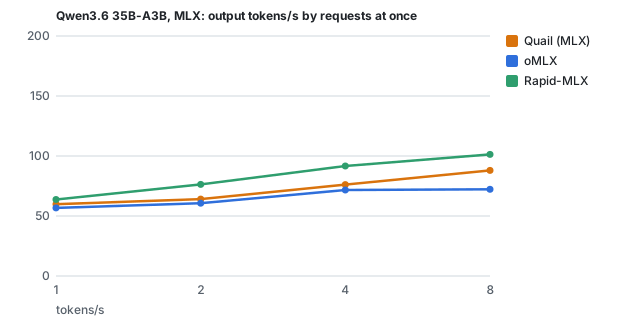
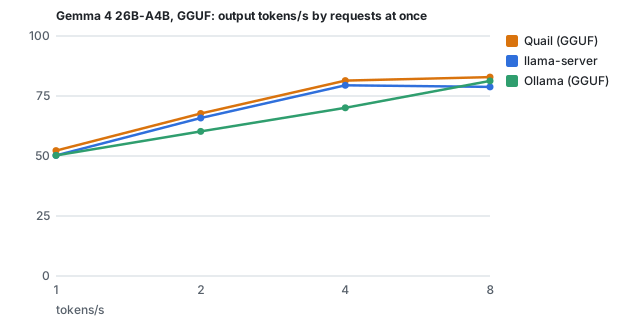
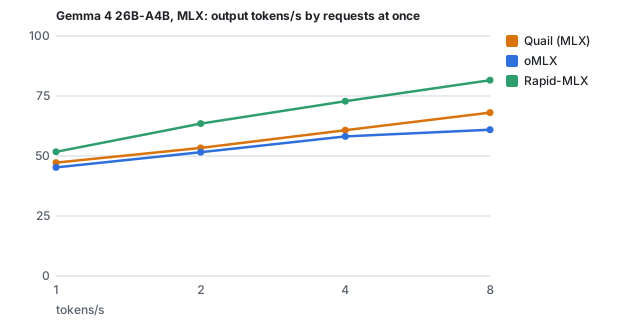
| Several requests at once | Yes: llama.cpp slots on GGUF, batched decoding on MLX source | One at a time by default (OLLAMA_NUM_PARALLEL); always one for some model families source | Yes, continuous batching (8 by default) source | Yes, continuous batching source | Yes, continuous batching (no limit by default) source |
|---|
| Prompt cache | Per conversation; MLX's also kept on disk source | In memory (MLX runner) source | In memory plus an SSD tier that survives restarts source | In memory, saved at shutdown source | Off by default; in memory plus an SSD tier when on source |
|---|
| Speculative decoding | Prompt lookup (fast when a reply repeats its prompt) source | MTP and DFlash on MLX source | DFlash and MTP, per model, off by default source | MTP, DFlash and more; on by default for some models source | DFlash, EAGLE-3 or MTP draft model; off by default source |
|---|
| Embeddings | Yes, and reranking, on GGUF and MLX source | Yes source | Yes, and reranking source | With an optional extra source | Yes source |
|---|
| Image generation | No (planned) source | No (experimental support removed in 0.32.6) source | No source | Yes, generation and edits (an optional extra) source | Yes, generation and edits source |
|---|
| Speech (transcription, speech) | No (planned) source | Transcription only (not in its docs) source | Both (the app includes the audio runtime) source | Both (an optional extra) source | Both, and translation source |
|---|
| MCP | No (planned: as a server, and its tools through the API) source | No source | MCP servers' tools through the API and its chat source | MCP servers' tools through its API and rapid-mlx chat source | MCP servers' tools in its chat, not through the API source |
|---|
| Starting coding tools | quail launch, and set-up snippets with a Test button source | ollama launch (about 25 tools) source | omlx launch, and one-click setup in its admin page source | rapid-mlx launch and agent setup source | Sets up and launches 10 terminal agents, and sets up 6 editors source |
|---|
| Usage data sent | None (the update check says which version is asking) source | None found (update checks send OS and version) source | Its benchmark uploads results with a hashed device ID source | On by default since 0.15.0 (can be turned off) source | None found (update checks go to GitHub) source |
|---|
| Platforms | macOS 14+, Apple silicon source | macOS, Windows, Linux source | macOS 15+ source | macOS source | macOS 26+, Apple silicon source |
|---|
| Licence | MIT source | MIT source | Apache-2.0 source | Apache-2.0 source | MIT source |
|---|
 Quail